Qixun Wang 王启迅
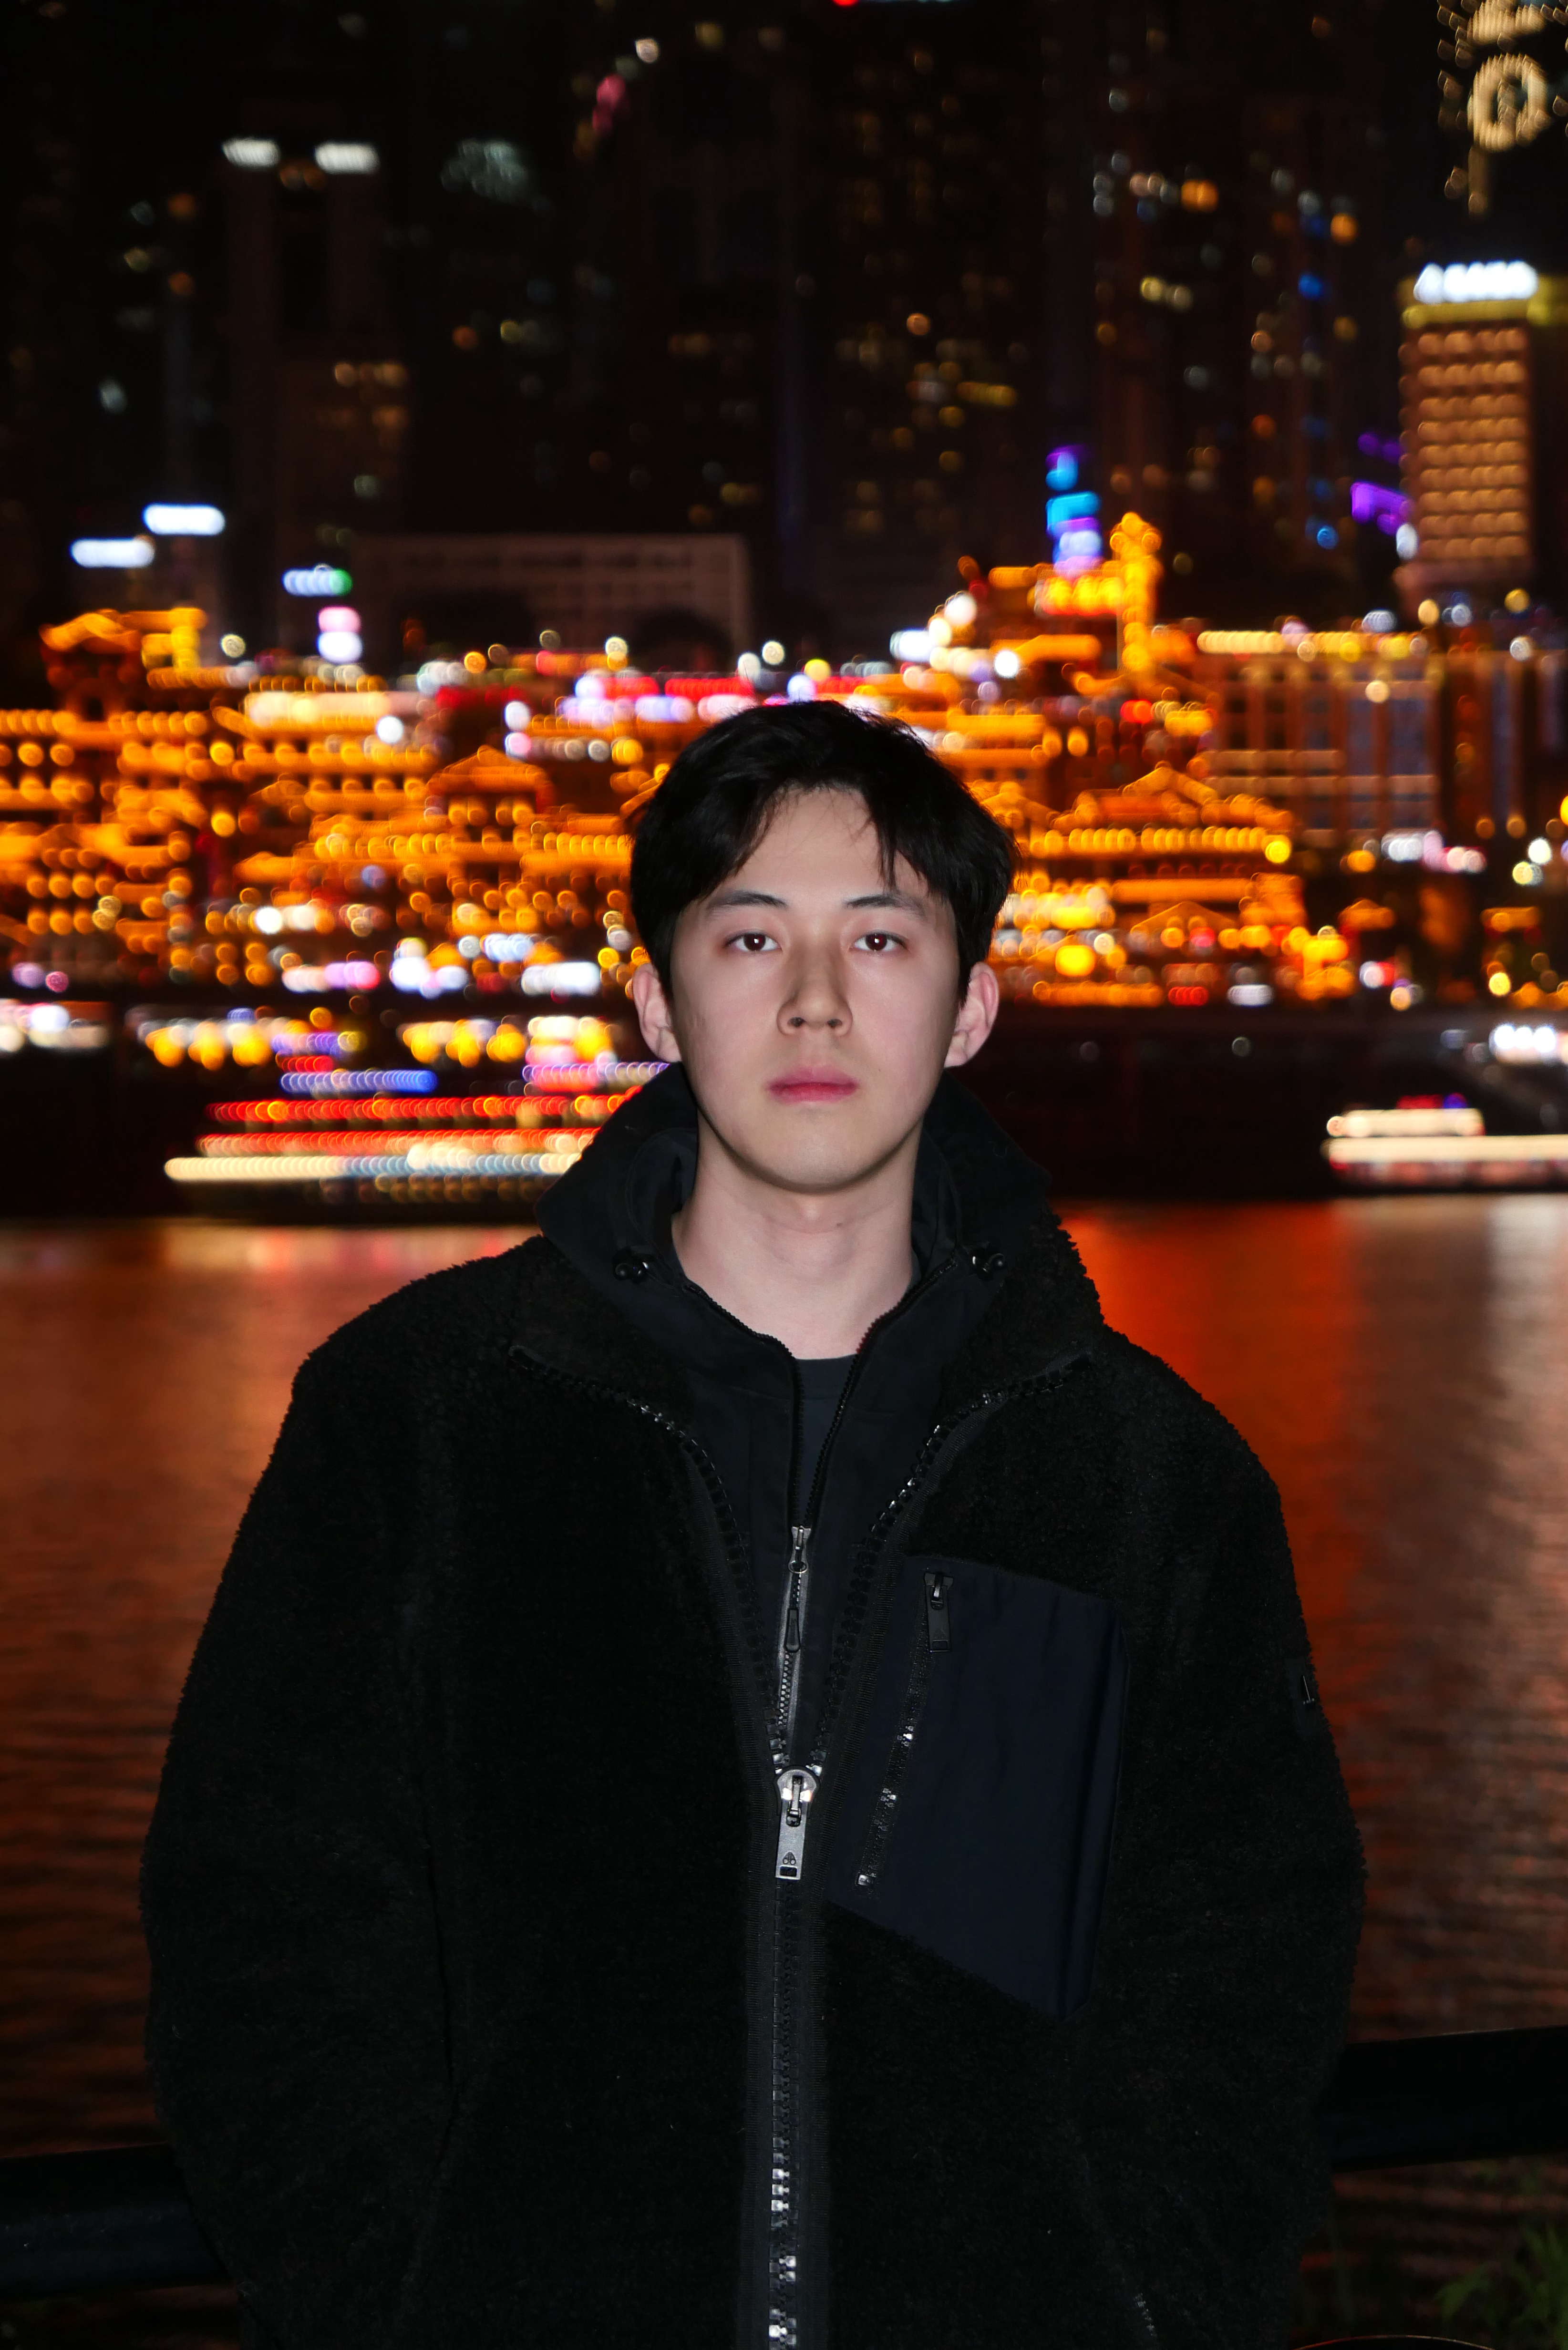
I am a fourth-year Ph.D. student in the School of Intelligence Science and Technology at Peking University.
My current research focuses on advancing the core capabilities of multimodal large language models (MLLMs) and their downstream applications. I am particularly interested in post-training methods that strengthen perception and reasoning, including reasoning in latent space (Monet, SLVR) and reasoning with visual tools (Beacon). Building on these capabilities, I explore MLLM applications in audio-video captioning and understanding (RefCaptioner), enhancing dynamic 3D world generation through programming, assessing the authenticity of AI-generated videos (Artifact-Bench, Verus-Insight), and GUI agents (FocusMem).
Previously, I focused on out-of-distribution (OOD) generalization, conducting theoretical analysis and designing algorithms for visual recognition (MAT & LDAT), graph tasks (CIA-LRA), and in-context learning in large language models (ICL-OOD). This background continues to inform my efforts to develop more robust and generalizable methods for MLLMs.
News
| July, 2026 | One paper, Beacon, on improving reasoning-mode adaptiveness and achieving genuine tool-induced performance gains in agentic visual reasoning, was released on arXiv. |
|---|---|
| May, 2026 | A paper entitled Artifact-Bench, which evaluates MLLMs for AI-generated video detection, was released on arXiv. |
| May, 2026 | Our paper Semantic-Enriched Latent Visual Reasoning was accepted to ICML 2026. |
| March, 2026 | I joined the Kling Team at Kuaishou Technology as a research intern. |
| February, 2026 | Two papers were accepted to CVPR 2026, covering reasoning in latent visual space and a benchmark for unified multimodal models. |
Selected papers (see full publication)
- arXivBeacon: Knowing When and Why to Perform Agentic Visual ReasoningarXiv preprint, 2026• Conduct a comprehensive analysis of reasoning-mode adaptiveness and tool-induced performance changes in existing agentic visual reasoning models.• Propose a novel training recipe that achieves state-of-the-art or competitive performance across 13 visual reasoning benchmarks, while improving reasoning-mode adaptiveness and delivering genuine tool-induced performance gains.
- CVPRMonet: Reasoning in Latent Visual Space Beyond Images and LanguageCVPR, 2026• Propose a new framework for multimodal latent reasoning, including dataset construction, SFT, and RL algorithms, achieving significant improvements on both in-domain and OOD visual reasoning benchmarks• 200+ GitHub stars
- ICLR
- NeurIPS
- NeurIPS Spotlight
- ICML
- arXiv
Experience
- Kling Team, Kuaishou Technology — Research Intern http://arxiv.org/abs/2604.03315(March 2026–present)
Working on multimodal agents.
Education
- Ph.D. Candidate in Machine Learning and Computer Vision, School of Intelligence Science and Technology, Peking University (2023–present)
- B.S. in Intelligence Science and Technology, EECS, Peking University (2019–2023)
Awards
- The Third-Class Scholarship of Peking University (2025)
- Merit Student at Peking University (2025)
- Outstanding Graduate of Peking University (2023)
- Yanchuang Capital Scholarship, Top 6% (2022)
- Merit Student at Peking University, Top 6% (2022)
- Academic Innovation Award at Peking University, Top 1% (2022)
- Award for Academic Excellence (2021)